Guides: deploy & operate
How to upgrade the proxyHow to upgrade the proxy
On this page
- Standard upgrade workflow
- Version compatibility
- TOML to YAML migration (mandatory before v1.4.1)
- One-liner (most installs)
- Step-by-step
- The S3-synced IAM database
- Upgrade to the separate config DB key
- Several instances and encryption (the encryption witness)
- Encryption at rest, format v2 (2.0.15)
- Storage facts only for readers of the whole folder (2.0.15)
- The conversion window replaces a read setting (2.1.0)
- Encryption needs atomic writes (2.1.0)
- A rule on
bucket/*no longer allows CreateBucket or DeleteBucket (2.1.0) - A replication destination that contains its source (2.1.0)
- A migrate of an aliased bucket (2.1.0)
- The Kubernetes operator (2.1.0)
- Common gotchas
- v0.9: per-backend encryption (breaking)
- Verify
- Related
This guide shows you how to move between DeltaGlider Proxy versions safely, including the one-time TOML-to-YAML config conversion (mandatory before v1.4.1) and the v0.9 encryption-config change. To go from 1.19 to 2.0, follow How to upgrade to 2.0 first, because that release has steps that you must do before the new version starts.
Standard upgrade workflow#
The proxy is a single stateful binary. Every upgrade has three steps: back up, swap, and verify.
-
Back up first. In the admin UI, open System → System (
/_/admin/system), and click Download backup in the backup card at the bottom of the page.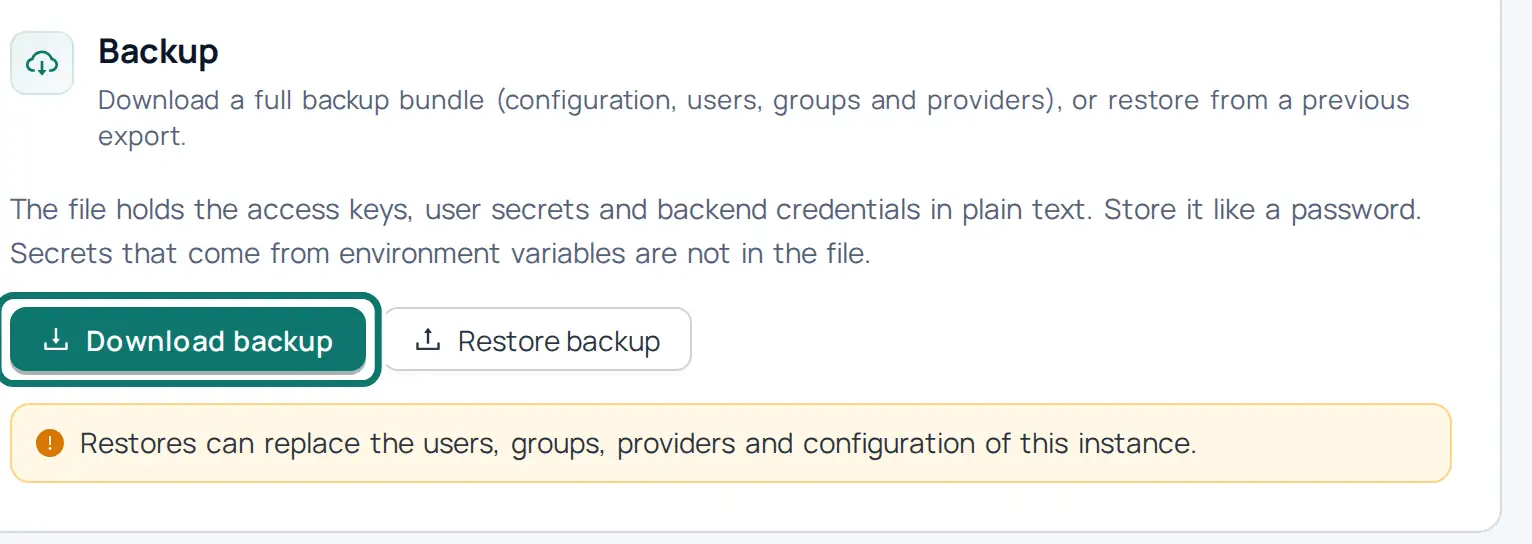
Or send a request to the API:
curl -b /tmp/admin.cookies \
  "https://s3.acme.example/_/api/admin/backup" \
  -o dgp-backup-$(date +%Y%m%d-%H%M%S).zip
The zip is atomic, and the proxy verifies its sha256 when you restore it. See the Admin API reference. Store the zip in a place that the upgrade itself cannot damage.
-
Roll the image/binary. For Docker:
docker pull beshultd/deltaglider_proxy:2.1.0
docker stop dgp && docker rm dgp
docker run -d --name dgp -p 9000:9000 \
  -v dgp-data:/data \
  -e DGP_BOOTSTRAP_PASSWORD_HASH=... \
  beshultd/deltaglider_proxy:2.1.0
Coolify, Kubernetes, and systemd have their own commands to pull and restart. The only requirement is that
/datapersists across the swap. -
Verify. Run four checks:
# Health curl -s https://s3.acme.example/_/health # Version matches the image you deployed curl -s -b cookies https://s3.acme.example/_/api/whoami | jq .version # A read against an existing object (regression test) aws --endpoint-url https://s3.acme.example s3 ls s3://releases # Admin session still works curl -b cookies https://s3.acme.example/_/api/admin/users | jq '.[] | .name' -
If something broke, the backup zip from step 1 imports atomically. In the admin UI, click Restore backup in the same card, select the zip, and choose what to restore. Or send it to the API:
curl -b cookies -X POST \
  -H "Content-Type: application/zip" \
  --data-binary @dgp-backup-...zip \
  https://s3.acme.example/_/api/admin/backup
Without a
modeparameter, the API restores everything, including the admin password of the backup. When the config file is read-only, a restore that includes the config answers409 config_file_read_only. How to back up and restore lists the modes.
Version compatibility#
Patch and minor upgrades inside one major version (for example from 1.18 to 1.19) need no extra steps. Read the changelog entries of the versions that you skip, because a minor release can still change a default.
Schema migrations of the config DB run automatically on the first start. The config DB is on schema v29 in 2.0. A migration is one-way: a binary refuses a config DB whose schema is newer than the one it knows, so an older binary cannot open a database that a newer binary migrated.
A major upgrade (for example from 1.19 to 2.0) has steps that you must do before the new version starts. Follow the upgrade guide of that version (How to upgrade to 2.0) and the release notes, and always export a Full Backup before you start.
TOML to YAML migration (mandatory before v1.4.1)#
TOML support was removed in v1.4.1. A v1.4.1+ proxy refuses to start when its config is a .toml file (named by DGP_CONFIG / --config or found on the default search path). The error is TOML configs are no longer supported (removed in v1.4.1). There is no deprecation warning anymore, and the config migrate subcommand is gone from v1.4.1+ binaries.
To convert the config once, run config migrate on v1.4.0 (the last release that ships it), point the server at the YAML file, and verify it. Only then upgrade to v1.4.1+.
One-liner (most installs)#
# On a v1.4.0 binary — config migrate no longer exists in v1.4.1+
deltaglider_proxy config migrate \
  /etc/deltaglider_proxy/config.toml \
  --out /etc/deltaglider_proxy/config.yaml
Point the server at the new file (with the --config flag, the DGP_CONFIG env var, or the standard search path). Restart the server and verify it. Then upgrade.
Step-by-step#
1. Run the migrator (on v1.4.0).
deltaglider_proxy config migrate /etc/deltaglider_proxy/config.toml \
  --out /etc/deltaglider_proxy/config.yaml
Without --out, the migrator writes the YAML to stdout, and you can pipe it to any destination. The migrator does not expand ${env:NAME} placeholders. It copies them verbatim.
2. Inspect the output. Canonical YAML uses the four-section shape:
# fragment
admission:
  blocks: []

access:
  access_key_id: ...
  secret_access_key: ...
  iam_mode: gui

storage:
  backend:
    type: s3
    endpoint: ...
    region: ...
  buckets: {}

advanced:
  cache_size_mb: 1024
The ... values stand for your own values. The session lifetime of the admin UI is not in the file: it is the environment variable DGP_SESSION_TTL_HOURS (default 4). The proxy refuses an unknown key, so do not add it to advanced.
The migrator keeps the SigV4 credentials (access.access_key_id / secret_access_key and the storage backend credentials), so you can use the output as it is. It strips only the infrastructure secrets (the bootstrap password hash and any encryption keys). Supply those again with env vars (see step 5).
3. Validate before applying. The config lint subcommand parses and validates the file without a request to the server:
deltaglider_proxy config lint /etc/deltaglider_proxy/config.yaml
# Exit: 0 = valid, 3 = I/O, 4 = parse, 6 = validation
Add this command to CI, so that CI catches drift in a pull request.
4. Point the server at the new file. File search order (first match wins):
DGP_CONFIGenv var./deltaglider_proxy.yaml./deltaglider_proxy.yml./deltaglider_proxy.toml(tripwire: startup fails on v1.4.1+)/etc/deltaglider_proxy/config.yaml/etc/deltaglider_proxy/config.yml/etc/deltaglider_proxy/config.toml(tripwire: startup fails on v1.4.1+)
If you keep both .toml and .yaml in the same directory, .yaml wins. Still, delete the .toml after you verify the YAML file. On v1.4.1+, a leftover TOML that the search matches first stops the startup, and the proxy does not ignore it silently.
5. Feed the stripped secrets back in. The migrator strips only the infrastructure secrets:
- Move
advanced.bootstrap_password_hashto theDGP_BOOTSTRAP_PASSWORD_HASHenv var. The base64-wrapped form avoids$escaping issues in Docker. - Move the per-backend encryption keys to
DGP_ENCRYPTION_KEY(singleton backend) orDGP_BACKEND_<NAME>_ENCRYPTION_KEY(named backends).
OAuth client_secret values live in the encrypted config DB, not in the YAML, so the migration does not touch them.
6. Delete the old TOML and upgrade. Once the v1.4.0 proxy runs cleanly from the YAML file, remove the .toml (it would trip the v1.4.1+ startup check) and roll to the new version.
The S3-synced IAM database#
The IAM database is separate from the YAML config. deltaglider_config.db (SQLCipher-encrypted SQLite) holds users, groups, OAuth providers, and mapping rules. The YAML config never carries IAM state (unless you run declarative IAM).
When upgrading across instances with DGP_CONFIG_SYNC_BUCKET set, the newer binary uploads after any mutation; older binaries (still running during a rolling upgrade) refuse a database with a newer schema, so they do not see the change. A newer binary reads the schema version of a synced database before it migrates it. It merges a copy from an older release after it migrates that copy, and the rows of that copy have an unknown change time, so a conflict with them goes to the copy in the bucket. Either:
- Upgrade all instances before you make IAM changes, or
- Accept that the instances on the older release lose the IAM changes of the rollout until they upgrade too.
Upgrade to the separate config DB key#
Earlier releases encrypted deltaglider_config.db with the bootstrap password hash. Current releases use a separate key: DGP_CONFIG_DB_KEY, or the key file deltaglider_config.db.key next to the database. The first start after the upgrade re-encrypts the database from the hash to the new key. That step works on a copy of the database, and the copy replaces the original only after it opens with the new key.
- One instance: nothing to do. The proxy generates the key file on the first start and re-encrypts the database with it. Back up the key file together with the database from then on.
- Several instances with
config_sync_bucket: generate one key (openssl rand -hex 32) and set it asDGP_CONFIG_DB_KEYon every instance before you start the new release. An instance with a sync bucket but without the variable refuses to start. Upgrade all instances together and avoid IAM changes during the rollout, because instances on the old release cannot read uploads under the new key. During the rollout, also setDGP_CONFIG_DB_ACCEPT_LEGACY_SYNC=trueon every instance. Without that variable, the new release refuses a synced database that an old instance wrote under the hash, because the hash is not a secret: it is in configuration files and backups, and anyone who can write to the bucket and knows the hash could plant an IAM database. Remove the variable and restart when every instance runs the new release. - Kubernetes operator with
bootstrapPassword.autoGenerate: the operator adds adbKeyto the<name>-bootstrapSecret and injects it into every pod. WithoutautoGenerate, addDGP_CONFIG_DB_KEYto your env Secret; the operator refuses to scale beyond one pod without it. - Before the upgrade, keep the hash that encrypted the database. The first start needs it once, to open the database. After the upgrade, the hash is only the admin password, and a change of the password no longer touches the database.
Several instances and encryption (the encryption witness)#
With config_sync_bucket set, this release keeps a witness of each bucket's encryption in the sync bucket, and an instance that disagrees with it refuses writes to that bucket (How to run multiple instances). This changes the behaviour of clusters that use backend-level encryption only, too:
- Upgrade every instance before you add an
encryptionblock to a bucket. An older release ignores the witness. - A backend key or mode that you change by editing the file or an environment variable and restarting the instances is not published by the restart. After such a rollout, every instance with the new key refuses all writes to that backend until you run
deltaglider_proxy witness publish backend:<name>once on one of them. A change made with a config apply is published at once and needs nothing else. - An instance that starts while the sync bucket does not answer refuses writes to every encrypting backend and to every bucket with its own
encryptionblock until its first check succeeds.
Encryption at rest, format v2 (2.0.15)#
This release replaces the format of proxy-side encryption (aes256-gcm-proxy). The earlier formats, aes-256-gcm-v1 and aes-256-gcm-chunked-v1 (body magic DGE1), have no reader and no migration path in this release, because no deployment used them. If a backend or a bucket of yours encrypted objects with an earlier release, those objects fail to read after the upgrade. Decrypt them before the upgrade, for example with a migrate job to a plaintext backend, and encrypt them again after it. Deployments without aes256-gcm-proxy have nothing to do for this change. The changes that you can see:
- Fail closed. In a bucket that encrypts, the proxy refuses every object that it cannot authenticate, with
500 InternalError. That includes a plaintext object, except the plaintext history that an open conversion window serves (why). - Starting to encrypt. An apply that makes a bucket with objects start to encrypt opens a conversion window and starts the re-encrypt job. Release 2.1.0 introduced this. See The conversion window replaces a read setting.
- Key ids. A backend key without
key_idgets the idfp-followed by 16 hexadecimal characters of the key's fingerprint. The backend name no longer takes part in the id. One key can have only one id on a backend; the proxy refuses to start with a config that gives one key two ids. - Stored metadata. An encrypted object stores no
dg-md5, nodg-encryption-key-id, and no SHA-256 of its content in clear. It storesdg-encrypted: aes-256-gcm-chunked-v1and adg-sealedvalue instead (Metadata markers). A script that readsdg-encryption-key-idon the raw backend must read the key fingerprint indg-sealedinstead. - Copies outside the proxy. An encrypted object that the backend copies to another bucket name or key no longer reads (Copies outside the proxy).
- Downgrade. A release before this one refuses to read the objects that this release encrypts. The objects are not damaged, and they read again after you upgrade once more.
With several instances and encryption, stop every instance and start all of them on the new release together. Do not roll the instances one by one, because an instance on the old release cannot read the objects that a new instance writes. Without a sync bucket, nothing stops an old instance from writing in the old format.
With config_sync_bucket set, the key check value of the encryption witness is now the key fingerprint, and a generated key id now starts with fp-. The witness entries that the old release published therefore differ from what the new release computes, and every new instance refuses writes to the encrypted buckets. When every instance runs the new release, publish the encryption once, on any instance, for each backend and each bucket with its own key:
deltaglider_proxy witness publish backend:hetzner-fsn1 db-archive --server https://s3.acme.example
The Encryption witness card on System → System lists the subjects that differ, and Publish all does the same. After the publish, an instance on the old release disagrees with the witness and refuses writes. Deployments without aes256-gcm-proxy can upgrade one instance at a time, as before.
Storage facts only for readers of the whole folder (2.0.15)#
This change applies to every deployment, with or without encryption. A delta is encoded against the reference of its folder, and that reference can hold data that another user uploaded. The storage facts of an object therefore tell how similar the object is to the other objects in its folder. For this reason, the proxy now sends these facts only to a principal that may read every object in the folder of the key.
The facts are these response headers and metadata keys:
- On the responses to
PutObject,CompleteMultipartUpload,CopyObjectand a browser form upload: the headersx-amz-storage-type,x-deltaglider-stored-size,x-deltaglider-ref-sha256andx-deltaglider-baseline. - On the responses to
HeadObjectandGetObject, and in each entry of ametadata=trueLIST: the delta keysx-amz-meta-dg-ref-sha256,x-amz-meta-dg-delta-size,x-amz-meta-dg-ref-path,x-amz-meta-dg-delta-cmdandx-amz-meta-dg-note. Objects that an older toolchain wrote can also carryx-amz-meta-dg-ref-keyandx-amz-meta-dg-source-name, and the proxy treats them in the same way.
A principal may read the whole folder when one of its Allow rules without conditions grants read on a pattern that ends in * and covers the folder (for example releases/*), and no Deny rule on reads can match a key in the folder. A principal that may only write, or that may read only some keys of the folder, now gets none of these facts. A reader without credentials, such as a reader of a public prefix or the holder of a presigned URL, also gets none of them.
Two kinds of clients see no change. With authentication: none, every request still gets the facts. A principal with read on the whole bucket, or on the whole folder of the key, also still gets them. If a script or a CI job reads one of these headers, make sure that its credentials have read on the whole folder. The full rule is in Storage facts on write responses.
The conversion window replaces a read setting (2.1.0)#
In earlier releases, a bucket that started to encrypt needed plaintext_reads: serve in its encryption block, so that the proxy served its plaintext history while the re-encrypt job converted it. Under serve, the proxy also served an object that someone put on the backend during the conversion. This release replaces the setting with a conversion window. A config write that makes a bucket with objects start to encrypt writes a sealed marker into the bucket and starts the re-encrypt job. While the window is open, clients read only the objects that the backend stored before the write, and the job closes the window when it converted every object (Plaintext objects in a bucket that encrypts).
The changes that you can see:
plaintext_readsis removed. The proxy no longer knows the field, withserveor withrefuse. A configuration that still has it fails to load, and the error names the field: the proxy does not start with such a file,config lintandconfig applyfail, and a section or document apply answers400. The fix is to delete the line from eachencryptionblock, as the steps below describe.- The confirmation is gone. The apply that started encryption on a bucket with objects no longer answers
422. The headerX-DGP-Confirm-Plaintext-Refusalis ignored, andconfig apply --confirm-plaintext-refusalis an unknown option, so a script that passes it fails. Remove both from your scripts. - A new
409. The same apply is refused with409when another job, for example a migration, holds one of the buckets. Wait for that job, or cancel it, and apply again. - The admin API. The bucket list and the backend summary no longer have
serves_plaintext. The bucket list reports the window ineffective_encryption.conversion, and a config write reports the conversions that it started inconversions(admin API). - A metadata backfill waits. While a bucket holds a conversion marker,
POST /_/api/admin/jobs/backfill-metadatafor that bucket answers409.
Do these steps before you start the new release, for each backend and each bucket whose encryption block has plaintext_reads:
- On the old release, run the re-encrypt job of each bucket that the block covers, and wait until it ends without failures:
POST /_/api/admin/jobs/reencryptwith{"buckets": ["<bucket>"]}. The job converts the plaintext history whileservestill serves it, so no read fails during the upgrade. - Delete the
plaintext_readsline from the configuration file. Find every line withgrep -n plaintext_reads deltaglider_proxy.yaml. - Start the new release with the edited file. Upgrade every instance that writes to the bucket: an instance on an older release ignores the window, and it serves and writes plaintext as before.
When a bucket still holds plaintext objects after the upgrade (you skipped step 1, or the job failed for some objects), the proxy refuses to read them, because the bucket encrypts and no window is open. A bucket that had serve already holds objects that the proxy encrypted, so it holds a key claim, and a restart opens no window for a bucket with a key claim (A conversion that a restart starts). Open the window and start the job yourself with POST /_/api/admin/jobs/reencrypt and {"buckets": ["<bucket>"], "open_window": true}. Clients then read the history that the backend stored before that request while the job converts it. Follow the job until the window closes, as in How to encrypt data at rest.
A restart does start the conversion of a bucket that never encrypted before. When you add aes256-gcm-proxy to the config file of a deployment that the Kubernetes operator, a Helm chart or a GitOps pipeline restarts, each bucket with plaintext objects, no key claim and no marker gets its window and its re-encrypt job at the start. The log names the run and the job.
With several instances, apply the change on every instance, and then let the job finish. An instance whose configuration does not encrypt the bucket yet writes plaintext into it, and the instances that encrypt refuse those objects after the cutoff. While the job runs, stop client writes to the bucket on every instance, or send them all to the instance that runs the job: the write gate of the job holds only on its own instance (A conversion on several instances).
Encryption needs atomic writes (2.1.0)#
Proxy encryption (aes256-gcm-proxy) now works only on a backend whose conditional writes the proxy proves with a probe. The proxy rewrites encrypted objects in place, each rewrite conditional on the version that it read, and a backend that ignores the condition could let a rewrite overwrite a newer client write (Encryption needs atomic writes). Native SSE modes are not affected.
The changes that you can see:
- Read-only buckets. A bucket that encrypts with the proxy on a backend that does not support atomic writes becomes read-only after the upgrade. An example is an encrypted bucket on a Backblaze B2 backend: B2 drops the connection on a conditional
PUT, and the probe reads that as "does not support". Reads keep working. Every write gets403 AccessDeniedwith a fixed sentence that says that the bucket is read-only and points to the migrate. A replication rule into the bucket showsdeferredwith the reason. The start log has a warning that names the read-only buckets. - Writes wait for the check (
503). The proxy must verify a backend before it accepts writes to the encrypted buckets on it. At start, it probes every S3 backend that holds such buckets at once, in parallel with the boot health check, and the start waits for these probes up to 3 seconds. A probe ends within 15 seconds. Until the probe of a backend ends, the writes to its encrypted buckets get503 SlowDown, which S3 clients retry, and reads are served. So after a restart, the writes to an encrypted bucket on an S3 backend can answer503for up to about 15 seconds. A filesystem backend needs no probe, so its buckets never wait. When the probe cannot reach the backend, the writes keep answering503and the proxy probes again after 5 seconds, doubling to every 60 seconds.GET /_/readyshows the state asatomic_writes(checking,unverified,supported,unsupported), and the state never makes the proxy not ready. - New
409refusals. A config change, a bucket create, a re-encrypt job (also Resume), a migrate and a restart that would turn proxy encryption on for such a backend are refused with409and anatomic_writesobject. - The probe runs on one instance too. Before, the capability probe ran only with
config_sync_bucketset. The proxy now probes, in the background, every backend that holds a bucket that encrypts with the proxy. - A form POST checks the signature first. A browser form POST into a bucket marked
replication_target_onlynow gets its403after the signature check, so an unsigned form gets the authentication error instead.
Check your backends before or right after the upgrade:
- Open Storage → Backends (
/_/admin/storage/backends), or sendGET /_/api/admin/backends. A backend whosecapability.verdictisnon-caslists its read-only buckets inread_only_buckets, and its card shows that they are read-only. A backend whose verdict isunknownsays that the proxy could not verify it; the writes to its encrypted buckets answer503until a probe succeeds. - For an
unknownverdict, fix the connection to the backend. The proxy probes it again by itself, at once when its health check sees the backend recover. To probe at once, click Check again on its card (POST /_/api/admin/backends/<name>/capability-probe). - For a
non-casverdict, move each read-only bucket to a backend with atomic writes with a migrate job: Make a read-only bucket writable again. The move out of a read-only bucket is allowed.
A rule on bucket/* no longer allows CreateBucket or DeleteBucket (2.1.0)#
A bucket-level request, such as a LIST request or CreateBucket, has no object key, so a rule with the resource releases/* does not match it on its own. In earlier releases, the proxy then checked the request again with the resource releases/, which releases/* matches, for every action. So a user whose only rule was {"actions": ["*"], "resources": ["releases/*"]} could also create and delete the bucket releases. This release makes that second check for every action except admin.
The changes that you can see:
CreateBucketandDeleteBucketget403for a user whose rules name onlyreleases/*. The same applies to the other bucket-levelPUTandDELETErequests, which needadmin.- The other bucket-level requests still work. A LIST request, a batch delete (
POST ?delete) and a browser form upload still need only a rule onreleases/*withlist,deleteorwrite.
When a user or a group must create or delete a bucket, add a rule whose resources hold the bucket name itself, for example {"effect": "Allow", "actions": ["admin"], "resources": ["releases"]}, or use * (Resources).
A replication destination that contains its source (2.1.0)#
A replication rule must not write into a prefix that contains its own source. An example is the rule releases/builds/nightly/ → releases/builds/. The destination builds/ holds the folder builds/nightly/, so the rule finds its own source objects in the destination. These objects have no twin at the source side, so a rule with delete replication deleted them, and its next run deleted the copies. Two bucket names that an alias points at one real bucket on one backend count as one storage, so a rule from releases to such a second name can have the same problem.
The changes that you can see:
- Such a rule does not run. The proxy still starts with a configuration that holds one, and it logs a warning that names the rule. Every run of the rule fails at its start with a failure entry, and the event consumer sends nothing for it.
config lintreports such a rule as an error (exit code6), and a config change that makes a new one is refused. A bucket change, such as a newalias, that makes one is refused too.
Before you upgrade, run deltaglider_proxy config lint deltaglider_proxy.yaml with the new binary. For each rule that it reports, give the rule a destination prefix outside its source, or another bucket (Replication reference).
A migrate of an aliased bucket (2.1.0)#
A migrate job blocks writes to the bucket that it moves, and it copies only that bucket. When another bucket name points at the same storage through an alias, the writes through that name were not blocked and not copied, and the cleanup deleted them. The proxy now refuses to start such a job: POST /_/api/admin/buckets/:bucket/migrate answers 409 Conflict, and the error names the other bucket names. Remove the alias before you move the bucket (How to move a bucket to another backend).
The Kubernetes operator (2.1.0)#
Operator 0.3.24 and later need a new ClusterRole and a new custom resource definition:
- The ClusterRole allows
patchon Secrets. The operator adds the config DB key (dbKey) to an existing<name>-bootstrapSecret that does not have it. With the old ClusterRole, that request got403, so every reconcile failed and the operator changed nothing in the cluster. - The ClusterRole allows the operator to manage NetworkPolicies, for the new
spec.router.networkPolicyfield. - The custom resource definition refuses a change of
spec.storageafter you create the resource, because a StatefulSet refuses a change to its volume claim templates.
Apply the new operator/deploy/crd.yaml first, and then the new operator/deploy/operator.yaml. The second file holds the ClusterRole and the operator image, so you get them together (How to scale out with the Kubernetes operator).
Common gotchas#
$in Docker env. Bcrypt hashes contain$. Use the base64-wrapped form (DGP_BOOTSTRAP_PASSWORD_HASH=JDJ5JDEyJGV...) or single-quote the value in compose files.force_path_style. MinIO needstrue; AWS S3 needsfalse. The migrator preserves whatever the TOML had.- Unknown bucket fields. A bucket policy refuses a field that the proxy does not know (see Bucket policies). Before you upgrade, run
deltaglider_proxy config lintwith the new binary on your config file. A misspelled bucket field, which an older release ignored, now stops the start with an error that names the field. - Implicit defaults. Fields absent from YAML take their default. Do not copy fields that were already at their default in TOML, because they clutter the canonical shape.
- Request rule order. The order of the request rules (
admission.blocks) matters. The migrator preserves order; reviewadmission:carefully. iam_mode: declarative. YAML becomes authoritative for IAM users, groups, OAuth providers, and mapping rules. Admin-API IAM mutations return 403;/config/applyreconciles the encrypted DB to YAML atomically. Seed from an existing DB withGET /_/api/admin/config/declarative-iam-export, or author IAM directly in YAML.
v0.9: per-backend encryption (breaking)#
v0.9 replaced the single global advanced.encryption_key field with per-backend encryption blocks. If you upgrade from a pre-0.9 pre-release, the proxy no longer recognizes the old field. It silently drops the key from any YAML that still carries the field.
The changes:
| Before (pre-v0.9) | After (v0.9) |
|---|---|
advanced.encryption_key: <hex> | storage.backend_encryption: { mode: aes256-gcm-proxy, key: <hex> } (singleton) or storage.backends[*].encryption: { ... } (list) |
DGP_ENCRYPTION_KEY env var | Same name for singleton path; DGP_BACKEND_<NAME>_ENCRYPTION_KEY for named backends |
Global encryption_enabled in GET /config | Per-backend encryption summary on each BackendInfoResponse |
Dedicated EncryptionPanel page | Subsection inside each backend card on the BackendsPanel |
To convert the pre-v0.9 YAML of a single-backend deployment, start from this YAML:
# not-proxy-config: pre-0.9 config, which current releases refuse
# OLD (pre-0.9)
advanced:
  encryption_key: 0123456789abcdef...
becomes:
# validate
# NEW (v0.9+)
storage:
  backend_encryption:
    mode: aes256-gcm-proxy
    key: "${env:DGP_ENCRYPTION_KEY}"   # move the hex to the env
Keep DGP_ENCRYPTION_KEY in the environment unchanged.
The upgrade to v0.9 did not change the objects on disk. Only the config location changed. Current releases no longer read the objects that v0.9 to 2.0.14 encrypted (see Encryption at rest, format v2).
If you did not configure encryption before v0.9, you have nothing to do. Your backends default to encryption: none.
To move from proxy-AES to SSE-KMS as part of the upgrade, do the upgrade first and keep your existing key. Then move each bucket to a new SSE-KMS backend with the migrate job, because the re-encrypt job does not write to SSE backends. The steps are in Recipe C: migrate from proxy-AES to SSE-KMS.
Verify#
After any upgrade or migration:
-
/_/healthreturns HTTP 200, and/_/readyreturns HTTP 200 (it checks the backends and the config DB). -
/_/api/whoami(with an admin session cookie, because anonymous requests do not getversion) reports the expectedversion. - An existing object downloads byte-identical:
aws s3 cp s3://releases/known-file ./out && sha256sum outmatches the known checksum. - The admin UI logs in with the bootstrap password (or OAuth) on the first try.
-
/_/admin/diagnostics/auditshows recent entries, so the audit ring fills. - Prometheus scrape returns valid metrics (if monitoring is wired up).
Related#
- How to upgrade to 2.0: the steps for the 1.19 to 2.0 upgrade
- How to back up and restore: the backup you take in step 1
- Configuration reference: the complete YAML field reference
- CLI reference:
config lintexit codes - Admin API reference: Full Backup export/import